Guides
How AI 3D model generators work, from NeRF to native 3D diffusion
From NeRF and DreamFusion to LRM, TRELLIS and Hunyuan3D: how AI turns text, sketches and photos into 3D meshes, and why the output needs retopology.
3 min read

Quick answer
How do AI 3D model generators work?
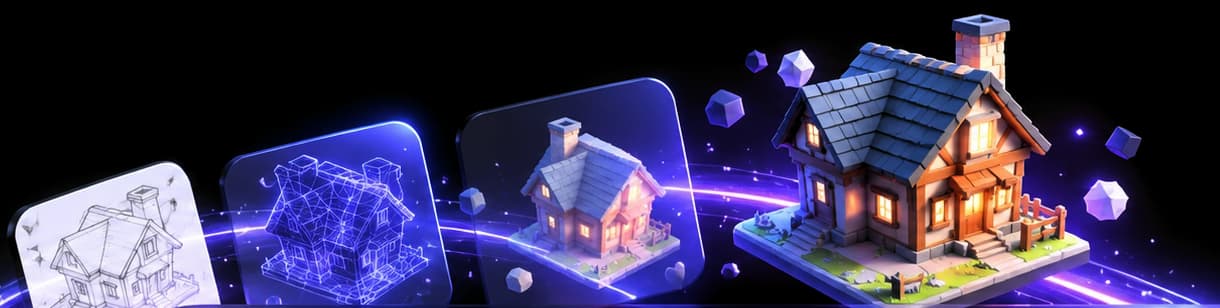
Modern generators are neural networks trained on large collections of 3D objects. Given a prompt or image, they predict a 3D shape in a compact learned form, convert it to a triangle mesh, then generate textures for it. Earlier methods instead optimised one object at a time using a 2D image model, which took far longer.
The core problem
A 3D model has to look right from every side. A 2D image generator only has to get one view right. The history of AI 3D generation is the story of how researchers got from one to the other, and every approach still leaves a mark on the models you get today.
Step 1: representing 3D with a network (2020)
NeRF ("Representing Scenes as Neural Radiance Fields for View Synthesis", 2020) showed that a small neural network could store a scene as a function: give it a point in space and a viewing direction, and it returns a colour and a density. Train it on photos of one scene and it renders convincing new views. NeRF was a reconstruction method, not a generator, but it gave the field a way to represent 3D that a network could learn.
Step 2: borrowing a 2D model's imagination (2022)
There was far less 3D training data than 2D. DreamFusion (2022) worked around that. It started from a random NeRF and repeatedly rendered it from random angles. A pretrained text-to-image diffusion model then judged whether each render matched the prompt, and the NeRF was nudged towards a better match. The technique is called score distillation sampling.
It worked, but slowly, because each object was a fresh optimisation. It also left a well-known artefact: the "Janus" problem, where an object grows a face on more than one side, because each view was judged on its own.
Step 3: models trained on 3D directly (2022 to now)
As 3D datasets grew, researchers trained networks that output 3D in a single pass:
- Point-E and Shap-E (OpenAI, 2022 and 2023) generated point clouds, then implicit functions, directly from text.
- LRM (2023), the Large Reconstruction Model, used a transformer to predict a 3D representation from a single image in one forward pass. Image-to-3D became fast.
- TRELLIS (2024) introduced a structured 3D latent that can be decoded into different outputs, including meshes, radiance fields and 3D Gaussians.
- Hunyuan3D 2.0 (2025) split the job in two: a diffusion model generates the shape, then a second model paints textures onto it.
That two-stage split, shape first, texture second, is now the common pattern, and it is why text-to-3D tools often generate an image first and then build the 3D model from it.
Step 4: turning the result into a mesh
Whatever the network predicts internally, a game engine needs triangles. Most pipelines sample the shape on a 3D grid and extract a surface with an algorithm in the marching-cubes family, which dates from 1987. The result is a dense mesh of evenly sized triangles that follows the surface closely and ignores the form's structure. That step is the main reason raw AI models are hard to edit. Why AI 3D models have messy topology goes into it.
Step 5: textures
Texturing models generate images from several viewpoints and project them back onto the mesh's UVs, or predict colours on the surface directly. Two artefacts come from this: visible seams where projections meet, and lighting baked into the colour. See AI-generated textures.
What this means when you use a generator
- The silhouette is the strong part. Modern models get overall shape right far more reliably than fine mechanical detail.
- The topology is the weak part, because of step 4.
- The input matters. One clear image with a plain background gives an image-to-3D model the least to guess. That is why image-to-3D and sketch-to-3D often beat a text prompt for control.
Vi3W adds a step after generation that most generators leave to you: automatic retopology, from high-poly to low-poly, before export. That targets the weak part of step 4 directly.
Last reviewed